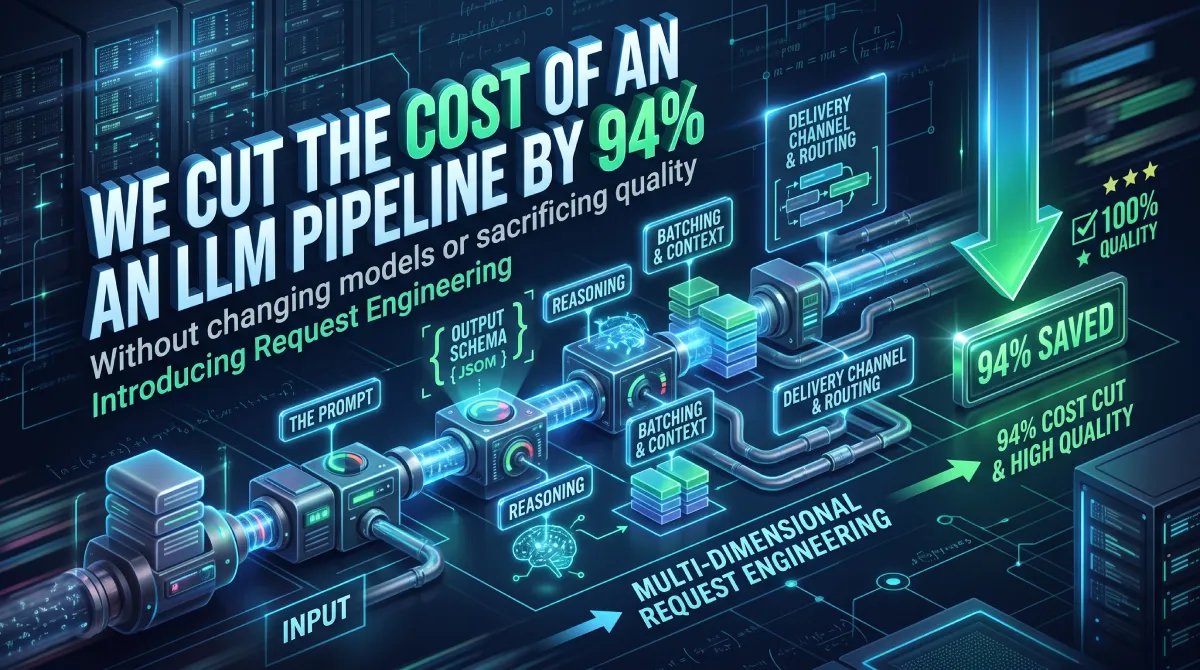
We cut the cost of an LLM pipeline by 94% without changing models or sacrificing quality. The savings didn't come from rewriting the prompt, but from how we made the call: what we sent, what we asked for back, how many times, and through which channel.
It´s called "Inference engineering" but i prefer call this request engineering: designing the whole request, not just the text. The prompt is only one part of a request to an AI model, and it tends to get too much attention given how capable today's frontier models are. The output schema, reasoning, model choice, context size, batching and delivery channel can matter far more, both for solving the task correctly and for keeping the cost per request down.
In this article I'll walk you through each of them, using a real (anonymized) case and its numbers. We optimized our requests through request and context engineering, cutting both the number of calls and the cost of each one.
1. We were spending far more than planned
The case: a periodic job that receives product reviews and performs two tasks with a small model (Claude Haiku 5.5):
- Extraction. For each review, the model returns the main product, up to five secondary entities and a category from a closed list.
- Disambiguation. Entities not found in our database are looked up in an external catalog. The catalog returns several candidates and the model picks the right one.
The budget was built like this: N reviews × 1 call × a few hundred tokens. But the actual bill turned out to be many times higher.
The underlying mistake (a very common one): you budget for calls, but you pay for tokens. And not all tokens cost the same, or even show up in the response.
2. Anatomy of a call: where the tokens go
An API call is not "the prompt". This is everything you pay for, in full, on every request:
| Part | What it is | Repeated on every call? | Priced as |
|---|---|---|---|
system | Fixed instructions | Yes | Input |
tools / schema | Structured output definition | Yes | Input |
| User message | The data to process + context | Varies | Input |
| Reasoning (thinking) | What the model thinks before answering | Varies | Output |
| Response | What you see | Varies | Output |
There are two ideas you need to keep in mind for everything that follows:
- Fixed content is paid on every call. A few hundred tokens of instructions and schema are nothing once, but they add up fast when multiplied by thousands of calls.
- Output is expensive. On Haiku 5.5 it costs $0.50 per million tokens versus $0.10 for input: five times more. And part of the output, the reasoning, doesn't appear in the response you read.
3. The prompt: clarity over length
Production work is very different from chatting with a model. A good production prompt is short, stable and free of duplication. Three rules:
Fixed instructions in system, data in the user message. In the original code, the categorization rules lived inside the user message, mixed with the text to analyze. Separating them tells the model what is a rule and what is data, and leaves an identical prefix across all calls, which is exactly what caching needs if it ever becomes worth enabling.
One rule, one place. The category list appeared twice: in the prompt text and in the schema's enum. If the schema already constrains the values, repeating them in the prompt only adds tokens. Keep in the prompt only what the schema can't express.
Examples (few-shot) only where the model fails. A couple of well-chosen examples fix recurring errors better than a paragraph of instructions. But every example is paid on every call: add them to improve quality, not out of habit.
BEFORE (user message, on every call)
Given the following text: "..."
Return an array with the entities...
Rules: 1... 2... categories: a, b, c, d... 3...

AFTER
system: fixed rules, once, without repeating the enum
user:   [id] text to analyze
4. Typing: stop parsing text
If your code calls trim(), strips quotes and compares against 'null', you're asking for free text where you need a value. That's exactly what our second call did:
let resultText = textResponse.text.trim();
if (resultText.startsWith('"') && resultText.endsWith('"')) resultText = resultText.slice(1, -1);
if (resultText.toLowerCase() === 'null') return null;
There are three ways to request output, from worst to best for production:
| Approach | Upside | Risk |
|---|---|---|
| Free text + "don't add explanations" | None | Unexpected formats, brittle parsing, retries |
| Tool with a JSON schema | Structured output | Without strict, the schema is only a suggestion |
Tool with strict: true or structured outputs | Output always validates against the schema | Requires additionalProperties: false and required |
The schema is part of the prompt too: a category enum, a type: ["string", "null"] field or an array with a description guide the model better than a sentence. And they save a lot of money indirectly, because every malformed response triggers a repeated call.
const PICK_TOOL = {
  name: 'pick_ids',
  strict: true,
  input_schema: {
    type: 'object',
    additionalProperties: false,
    required: ['picks'],
    properties: {
      picks: { type: 'array', items: {
        type: 'object', additionalProperties: false,
        required: ['entity', 'id'],
        properties: { entity: { type: 'string' }, id: { type: ['string', 'null'] } },
      }},
    },
  },
};
5. The reasoning you pay for but never see
This task didn't need "thinking" (the model's reasoning) turned on. This is where we got our biggest surprise: 31% of the spend was reasoning nobody had asked for.
Let me explain: recent models think by default. On Claude Haiku 5.5, adaptive thinking is on at a medium effort level even if you don't ask for it. That reasoning is billed as output, at output prices. And by default you don't even get its text back: all you see is an empty block and the token count.
Our disambiguation call asked for a single identifier, about 20 tokens of response. But the model reasoned for about 400 tokens before answering. We were paying for 20 times more output than we actually used.
The extraction call, on the other hand, didn't have this problem: it used a forced tool (tool_choice: {type: 'tool'}), and on this model a forced call goes straight to the tool, without thinking first.
How to keep it under control:
- Check
usage.output_tokensagainst what you actually read. A large gap means hidden reasoning. - Lower the effort:
output_config: { effort: 'low' }. The model thinks less and may skip reasoning entirely on simple tasks. - Turn it off where it adds nothing, if the model allows it (
thinking: { type: 'disabled' }), or force the tool. - Set
max_tokensto what you expect. Reasoning counts toward that limit.
When is it worth letting the model think? When the task has multiple steps, real ambiguity or a high cost of getting it wrong. Picking an identifier from five well-described candidates isn't one of those. Classifying with subtle rules might be: there, enabling reasoning can pay off. But measure quality with and without reasoning before deciding.
6. Choosing a model: the cheapest one isn't always cheaper
When choosing a model, we almost always ask "how much does a million tokens cost?", but that's not what matters. The question you should be asking is "how much does each correctly completed task cost?". Three things to keep in mind:
- Retries and errors. A cheap model that fails 10% of the time, forcing you to retry or review by hand, can end up costing more than a better one.
- The tokenizer. Each model generation counts tokens its own way. The same text can take around 30% more tokens on one model than on another. If you budgeted with one model and migrated to another, recount with the token counting API.
- Effort is a lever too. Before building a model cascade ("small model first, big one if it's unsure"), try the stronger model at low effort. Recent models with little reasoning often perform as well as earlier models with high reasoning, and a single model is easier to maintain and to cache.
In our case the small model was the right choice, because we only had to extract and pick among candidates, which are well-bounded tasks. What was failing was the way we called the model, not which model we chose.
7. Fewer calls, more work per call
The single biggest lever was trimming the context: 52% of the savings.
Send what the model needs to decide, not everything you have
To pick a candidate, we were sending the full list of options from the external catalog: ten results with long descriptions, images, URLs, licenses and scores, serialized with JSON.stringify(data, null, 2). Around 3,500 tokens per lookup. Five candidates with four fields were enough to decide:
const trim = items => items.slice(0, 5).map(({ result: r }) => ({
  id: r['@id'],
  name: r.name,
  type: r['@type'],
  desc: (r.description || '').slice(0, 160),
}));

JSON.stringify(trim(items)); // no indentation
Result: from about 3,500 to about 225 tokens per lookup. Watch out for indentation: spaces and line breaks are tokens too, and the model doesn't need them.
Group items into a single request
This is one of the keys to cutting costs on LLM API calls. We made one call per review to extract the entities, and another for each unresolved entity. So every call paid for the instructions and the schema all over again (around 400 fixed tokens). Our solution:
- Extraction: 20 reviews per call, each with its own
id, and a schema that returns an array of results. The fixed cost per review drops from about 600 tokens to about 65. - Disambiguation: all pending entities for a review in a single call, with an array of answers.
The limit on grouping is quality: with batches that are too large, the model starts mixing up or skipping items. Between 10 and 30 short items per call usually works well, but check with your own data that every input id gets its output.
8. Batch: half price in exchange for patience
Anthropic's Message Batches API processes the same requests asynchronously at a 50% discount (OpenAI and other providers offer something similar). It usually finishes within minutes, but the delivery commitment can stretch to a maximum of 24 hours.
| Is batch a fit? | Yes | No |
|---|---|---|
| Type of process | Periodic (hourly, nightly) | Interactive, the user is waiting |
| Acceptable latency | Minutes or hours | Seconds |
| Volume | Tens to thousands of requests per run | One-off requests |
Our pipeline is a fit because it's periodic. It's designed in two phases, since the second depends on the first:
- Extraction batch.
- Lookup in the database and the external catalog with the extracted results.
- Disambiguation batch with whatever is still unresolved.
const batch = await client.messages.batches.create({
  requests: groups.map((g, i) => ({ custom_id: `extract-${i}`, params: buildParams(g) })),
});
// poll batches.retrieve(batch.id) until processing_status === 'ended'
for await (const r of await client.messages.batches.results(batch.id)) {
  if (r.result.type === 'succeeded') save(r.custom_id, r.result.message);
  else requeue(r.custom_id); // errored / expired
}
Three rules to avoid surprises:
- Results arrive in any order. Always key by
custom_id; don't rely on the position of items in the response. - Handle
erroredandexpired. A request that doesn't finish within 24 hours expires and has to be requeued. - The parameters are the same. Everything covered in the previous sections (typing, reasoning, grouping) applies unchanged. The 50% batch discount stacks on top of the savings from optimizing the requests.
9. Caching: the optimization that can backfire
Prompt caching stores the fixed prefix of the request (tools, system and everything that doesn't change) and charges a tenth of the price for it on subsequent calls. It comes with three conditions:
- The prefix must be byte-for-byte identical. A date or an ID inside the
systemprompt breaks it. - It must exceed a minimum token count, which depends on the model (in our case, 512 tokens on Haiku 5.5). Below that it can't be cached, and watch out: you get no error telling you so.
- Writing costs more than reading: the first time you pay 1.25× the input price; reads cost 0.1×. In plain terms: you pay 25% more on the first request and save 90% on the following ones.
Our prefix was about 350 tokens. The temptation is obvious: what if I pad it to 512 so it gets cached? To settle the question, we tested it. Here's what happens with a test run of 100 calls, measured in token equivalents at the input price:
| Scenario | Token equivalents |
|---|---|
| No cache: 350 × 100 | 35,000 |
| Padded to 512, staggered calls: 1 write + 99 reads | ~5,700 |
| Padded to 512, 100 calls in parallel | ~64,000 |
In parallel it costs almost twice as much. The cache only becomes available once the first request has started responding: if you fire them all at once, they all miss and they all pay for the write. To use it properly, you need to warm it up first with a single request and then send the rest.
And in our case, after grouping 20 reviews per call, the prefix is paid only a handful of times per run. The possible savings amount to cents per month, so it isn't worth "rigging" the request just to enable prompt caching.
In short: caching shines with long, repeated prefixes (documents, manuals, conversation histories), not with short prompts. If you add tokens, make them examples that improve quality; if that takes you past the minimum, the cache becomes a bonus that will save you a lot of money. And always check usage.cache_read_input_tokens: if it stays at zero, something is invalidating the prefix and breaking the cache.
10. Results: before and after
The cost per 1,000 reviews drops from $1.27 to $0.08: 94% less. Trimming the context and turning off hidden reasoning account for 83% of the savings. Grouping calls contributes little direct savings, but cuts the number of requests to a third.
| Per review | Input (tokens) | Output (tokens) | Calls per 1,000 reviews |
|---|---|---|---|
| Before | ~7,900 | ~960 | ~3,000 |
| After | ~765 | ~150 | ~1,050 |
Assumption: an average of two entities per review that need disambiguation. At 100,000 reviews a month, the bill goes from about $127 to $15 in synchronous mode, or to about $7.60 with batch.
11. Request engineering checklist
Here are ten questions to audit any call you're designing before it goes to production:
- Are the fixed instructions in
systemand the data in the user message? - Does any rule appear twice (in the prompt and in the schema)?
- Is the output structured and strict, or are you parsing free text?
- Do you know whether the model is reasoning? Do you compare
output_tokenswith what you actually read? - Is the effort level right for the task, or just the default?
- Are you sending only the fields the model needs to decide? Without indentation?
- Could you process several items in a single call?
- Is anyone waiting for the response in real time? If not, why aren't you using batch?
- Is your prefix long and stable enough to cache? Are you firing calls in parallel?
- Do you measure
usageper call and calculate cost per completed task, not per request?
The prompt matters, of course, but it's only one part of the request. Your real bill will depend on everything else. So my advice is to stop obsessing over "prompt engineering", which is very much a thing of snake-oil LinkedIn posts from 2025: models have come a long way in recent months, and it's no longer worth spending so much time on user prompting. Learning "request engineering", "context engineering", or how to set up and tune a good "harness" for your agent will be far more useful than any cheap prompting guide you'll find online.
12. Official resources for learning "request/inference engineering" and properly designing API calls to AI providers
Anthropic: Optimizing for cost and intelligence
https://platform.claude.com/docs/en/about-claude/models/optimizing-for-cost-and-intelligence
This resource distinguishes between levers that save costs without sacrificing quality (prompt caching, trimming input tokens, batch processing, reviewing legacy prompts) and those that involve a trade-off between quality and cost (model selection, effort settings, output limits, multi-model strategies). It also explains how to measure the cost per completed task based on your specific workload.
OpenAI: Cost optimization
https://developers.openai.com/api/docs/guides/cost-optimization
This covers strategies such as making fewer requests, using fewer tokens, and selecting smaller models. It also includes information on the Batch API and "flex processing" a lower-cost, lower-priority mode for requests that are not time-sensitive.